Table of Contents
The Challenge: Serverless Data Processing
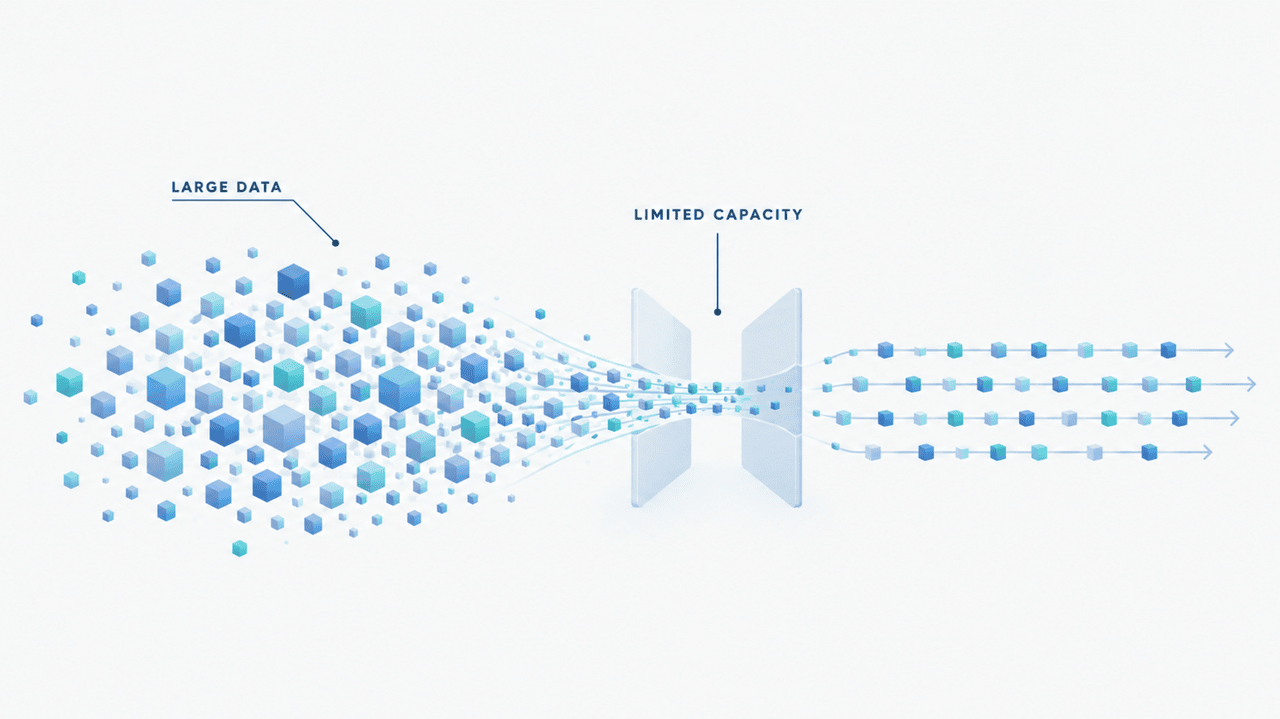
Imagine having to extract and process a large amount of data using the fewest possible resources. It sounds like a great challenge, almost paradoxical, yet it was one of the most stimulating problems I have faced and one that I would like to talk about in this article.
The context was a microservice developed in Go and deployed via IaC on an AWS-based Serverless architecture. The stack leveraged several services, but the ones I will focus on are two: Lambda Functions and the NoSQL database DynamoDB.
In short, the goal was to extract raw data from this database, process it, and finally send it to a third-party service via API calls. All these operations had to be executed periodically and automatically.
Constraint Analysis
Before proceeding, I started a preliminary analysis of the problem to plan the actions to take during implementation and in the subsequent testing phases.
The first constraint identified, intrinsic to the project, was exactly the architecture already adopted within the cloud infrastructure. The new feature therefore had to be defined within this pre-established boundary, leaving the identification of the most suitable AWS service as the main area of choice.
I decided to use Lambda. Running a process that could last, at least theoretically, in the order of minutes, but had a weekly schedule, made it clear how a pay-per-use model could be more convenient compared to other solutions with fixed costs and pre-allocated resources. In the latter case, in fact, the periods of inactivity would have been very long and would have led to a waste of resources.
The second constraint to respect was instead a direct consequence of the first choice: the optimized use of computational resources, such as CPU and memory, while respecting the maximum timeout imposed for Lambda Functions.
In addition, on the database side, there was also the need to keep DynamoDB read capacity consumption under control.
This led to the need to design a concurrent processing strategy that allowed data to be processed efficiently, without compromising the execution time of the function.
My focus therefore fell on using the Worker Pool pattern in Go and on concurrent retrieval, together with an optimized data extraction from DynamoDB.
The last constraint, on the other hand, concerned sending the large amount of processed data to the third-party service, which had to respect a specific format and, above all, a payload limit, also taking latency into account.
The decision to split the data into batches to be sent with each request was therefore the most direct and effective solution.
Workflow Planning
Once this first phase of analysis was completed, I moved on to planning the actual workflow, from implementation down to final testing. I divided the development into three main sections: retrieving data from DynamoDB, processing it, and finally sending it via RESTful APIs.
The approach was incremental, progressively testing the implemented features with a small amount of test data in a dedicated development environment. The initial focus was on the correctness of the implementation and on data consistency.
Once this first phase was finished, the next step involved using large volumes of real data, but still in a non-production environment. The goal was to verify that all the analyzed constraints were respected, evaluating performance through metrics collected from dedicated logs added to the code.
Infrastructure Configuration
On an operational level, the initial step was configuring the Lambda Function via IaC, defining the necessary parameters. The most relevant ones were memorySize and timeout.
The first was particularly important because, besides determining the memory available for the function, it also influenced the amount of CPU available to it. The second one, instead, could not exceed 900 seconds (15 minutes).
Initially, I set these two parameters with indicative and relatively low values, so I could proceed with the implementation. Once I moved to the final testing phase on real data, the approach was to tune these values, along with other parameters used in the codebase that I will describe later.
Two other fundamental elements of the infrastructure were also involved: the IAM role associated with the Lambda and EventBridge.
The IAM role was necessary to define the function’s permissions, from accessing the DynamoDB tables down to writing logs to CloudWatch.
I used EventBridge to schedule the Lambda and automatically start the process according to the expected schedule.
Concurrency in Go: The Worker Pool Pattern
Now let’s get into the heart of the matter, which is how I handled concurrency for data extraction and processing. The pattern I used is the Worker Pool.
I deliberately excluded the sending phase from this strategy, preferring to execute it afterwards, once the data extraction and processing were completed. This way I could properly prepare and validate everything before proceeding with sending it to the external service.
Go provides so-called goroutines, very lightweight execution units managed by the runtime and suitable for the concurrent execution of multiple tasks. Each worker was implemented through a goroutine. By leveraging Channels and WaitGroups, I could distribute the tasks among a controlled number of workers and synchronize their completion.
The problem was that it didn’t make sense to spawn an indefinite number of workers, but I had to set a fixed number, so that there were enough to handle the large amount of data, but not so many as to saturate all available resources. This was therefore another parameter to be tuned in the final testing steps.
To structure this management, I essentially used three Channels. The first, called taskChannel, allowed the workers to pick up tasks, while the processing result was put into the resultChannel. All this with the addition of an errorChannel, used to handle any errors during processing. The WaitGroup allowed me instead to wait for the completion of all workers before proceeding to the next phase.
With this approach based on the Worker Pool, the target was clear: reducing the total execution time of the Lambda. However, to keep the memory usage of the Lambda itself contained, another crucial focus became efficient data extraction. This need was combined with the other important goal: containing DynamoDB’s read capacity consumption, which represented a further constraint to take into consideration.
DynamoDB Optimization
Now comes the other central aspect, namely DynamoDB. Here I first had to identify the most suitable access pattern, keeping in mind the constraints on resources.
As anticipated, one of the fundamental elements to consider was the consumption of Read Capacity Units (RCUs), where lower consumption translated into a more efficient use of read capacity.
The choice of the access pattern therefore had to take into account this constraint, but also the structure of the data I had available. For example, if I had to retrieve “primary” data without having an access pattern that allowed targeted access, the solution, although not ideal, was the Scan.
If instead I had to retrieve “derived” data from previously obtained information and the table architecture allowed it, I could use a Query, identifying the items through the PartitionKey value and possibly further restricting the result through a condition on the SortKey. In this last case, any GSI/LSI indexes could also be used to access the data through a different access pattern.
Another aspect to consider concerned what data I specifically needed. This was linked to the other goal, namely minimizing the Lambda’s memory consumption. It was therefore necessary to avoid retrieving all the item attributes, focusing only on those that would actually be used in the processing inside the workers.
And this is where ProjectionExpression came into play, which allowed me to specify which attributes to retrieve from DynamoDB. I would like to explicitly point out that this did not reduce the consumed RCUs: the advantage mainly concerned the amount of data transferred and kept in memory by the Lambda.
Finally, one last aspect remained to be managed. DynamoDB imposes a limit of 1 MB of evaluated data per single Scan or Query operation, making pagination necessary when the evaluated data exceeds this limit. This is where LastEvaluatedKey solved the issue.
Retrieval Parallelization and Pipeline
At this point I considered a couple of additional strategies to improve data retrieval, linking them also to the Worker Pool topic.
The first concerned the Scan case. The idea was to reduce the Lambda’s execution time by splitting the Scan into many segments, assigning each one to a worker. This way, each goroutine executed the Scan for that specific segment. This choice, while potentially reducing execution time significantly, would however have increased the parallelism of read operations and therefore the peak RCU consumption, increasing the risk of throttling.
The second strategy, which proved to be the winning one, instead concerned the use of a dedicated Channel in which to progressively insert the data as it was retrieved. This way I created a sort of continuous stream through the channel, avoiding having to wait for the completion of the entire extraction by the database before starting to process the results. This decoupling therefore allowed the extraction and processing to overlap, reducing the workers’ wait times. The downside of this approach was the potential accumulation: an extraction that was too fast compared to the workers could in fact have progressively increased memory consumption.
Final Checks and Considerations
Without dragging this out further, I would now like to briefly talk to you about the final post-implementation phase.
I ran the tests in a specific pre-production environment using data volumes similar to the real ones. In this step I leveraged the logs I had inserted into the code, reviewing them in CloudWatch to verify the Lambda’s behavior and the consistency of the results.
As the amount of data increased, it progressively became necessary to tune the parameters described earlier. Actually, the number of workers was adjusted very few times compared to what I had initially imagined.
The main point of reference during this phase was the Lambda execution time, since, from an operational point of view, it was the most critical metric: exceeding the maximum timeout would have in fact rendered the entire feature unusable.
Surprisingly, this value turned out to be very low, in the order of a few minutes for the entire cycle across the three steps.
Memory and RCUs had been considered in the design and in the previous implementation choices, but in the final phase they did not require any significant further optimization.
Any errors in the three stages were tracked in the logs without interrupting the execution of the process, allowing me to later verify in CloudWatch which data had been processed correctly and which had presented anomalies.
The architecture also left room to handle larger volumes by increasing the number of workers and, if necessary, the memory available for the Lambda.
The subsequent checks with real data finally confirmed that the solution was working as expected.
Last Thoughts
For me it was a really interesting experience, which allowed me to dive into and evaluate in detail all these aspects we discussed in this article.
It was also an opportunity to practically confront the dynamics of a serverless cloud architecture, where the different characteristics of the services used directly influence the design choices and the way a solution must be implemented.
In the end, it’s all a game of balance and trade-offs between constraints, parameters, and resources.
Thanks for reading.